Hi, my name is Wenhao Wu (吴文浩). I am a third-year master's student at Nanjing University, supervised by Prof. Zhi Wang (王志). My research interests focus on Large Language Model Agents, Retrieval-Augmented Generation, Meta Reinforcement Learning, and Embodied AI.

🔥 News

  • 2026.09: Darwin Agent released HarnessPAI, a technical report on an evolving harness for Physical AI.
  • 2026.08: Darwin Agent won 1st place in the Open Track of the IJCAI-ECAI 2026 CAR-bench Challenge.
  • 2026: One paper was accepted by ICML 2026.
  • 2026.01: Completed a research internship at Huawei Noah's Ark Lab.
  • 2025: Two papers were accepted by NeurIPS 2025.
  • 2024: One paper was accepted by NeurIPS 2024.

📝 Publications

🤖 Language Agents, RAG

🦾 Embodied AI

HarnessPAI: An Evolving Harness for Physical AI
Xin Wang*, Wenhao Wu*, Menghao Zhang*, Zhi Wang, Kun Shao, Jian Luan, Yang Li, Qing Li, Shangding Gu, Huichi Zhou, Shuqing Shi, Fei Ni, Shuo Lu, Weicheng Meng, Kang Li, Jin Wu, Kang Zhao, Shangmin Guo, Gen Li, Yongqiang Tang, Zhizhong Zhang, Yuan Xie, Heng Qu

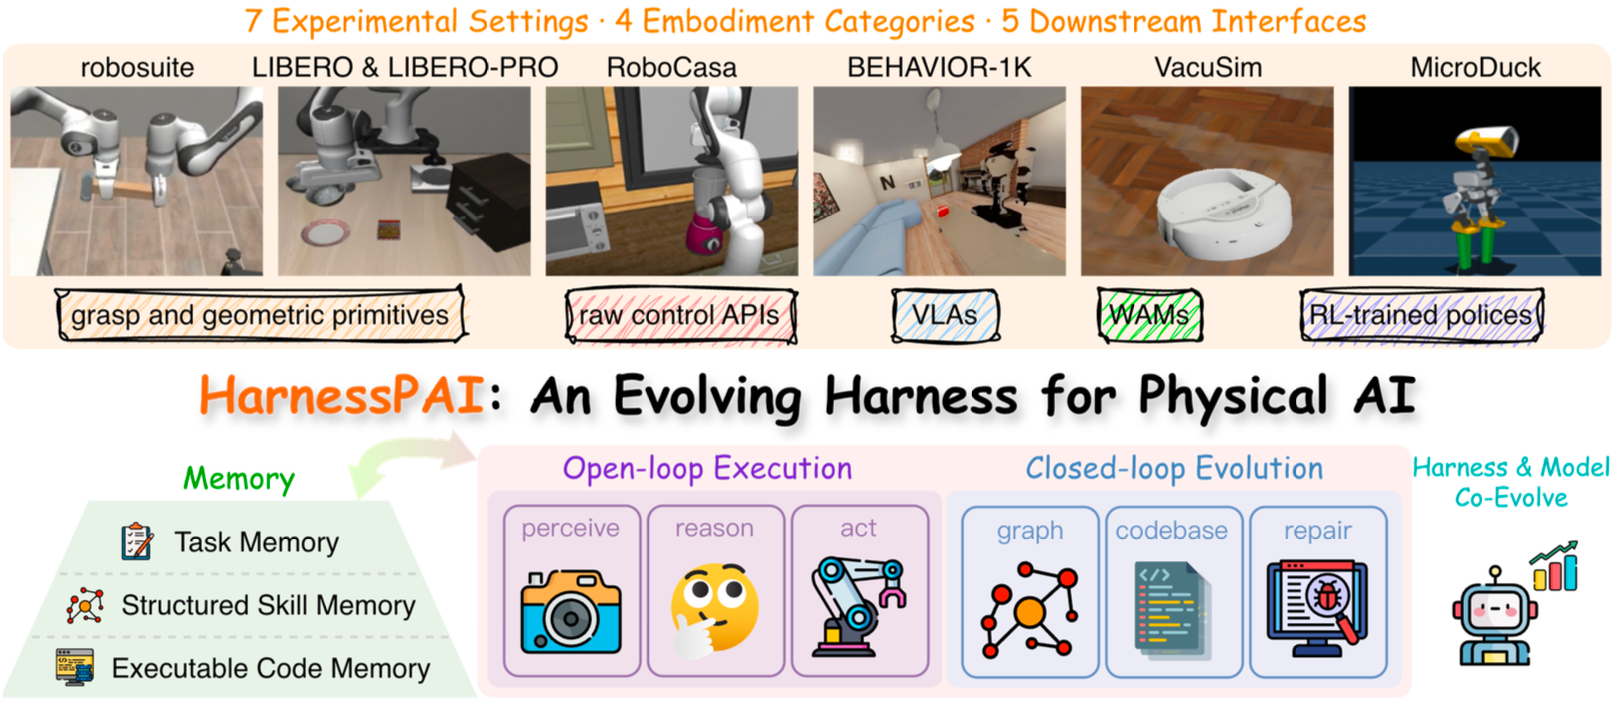
Introduces a model- and embodiment-agnostic harness for Physical AI in which the harness and action model co-evolve through rollout feedback: action primitives are organized into executable programs, failures are distilled into reusable skills, and the system improves without retraining the underlying action model.

Look Before You Leap: Distilling Tree Search into Action Evaluation for Frozen VLA Models
Xinyi Xie, Zican Hu, Zhanyu Liu, Yicheng Dong, Wenhao Wu, Haoran Li, Chunlin Chen, Zhi Wang*, Pichao Wang

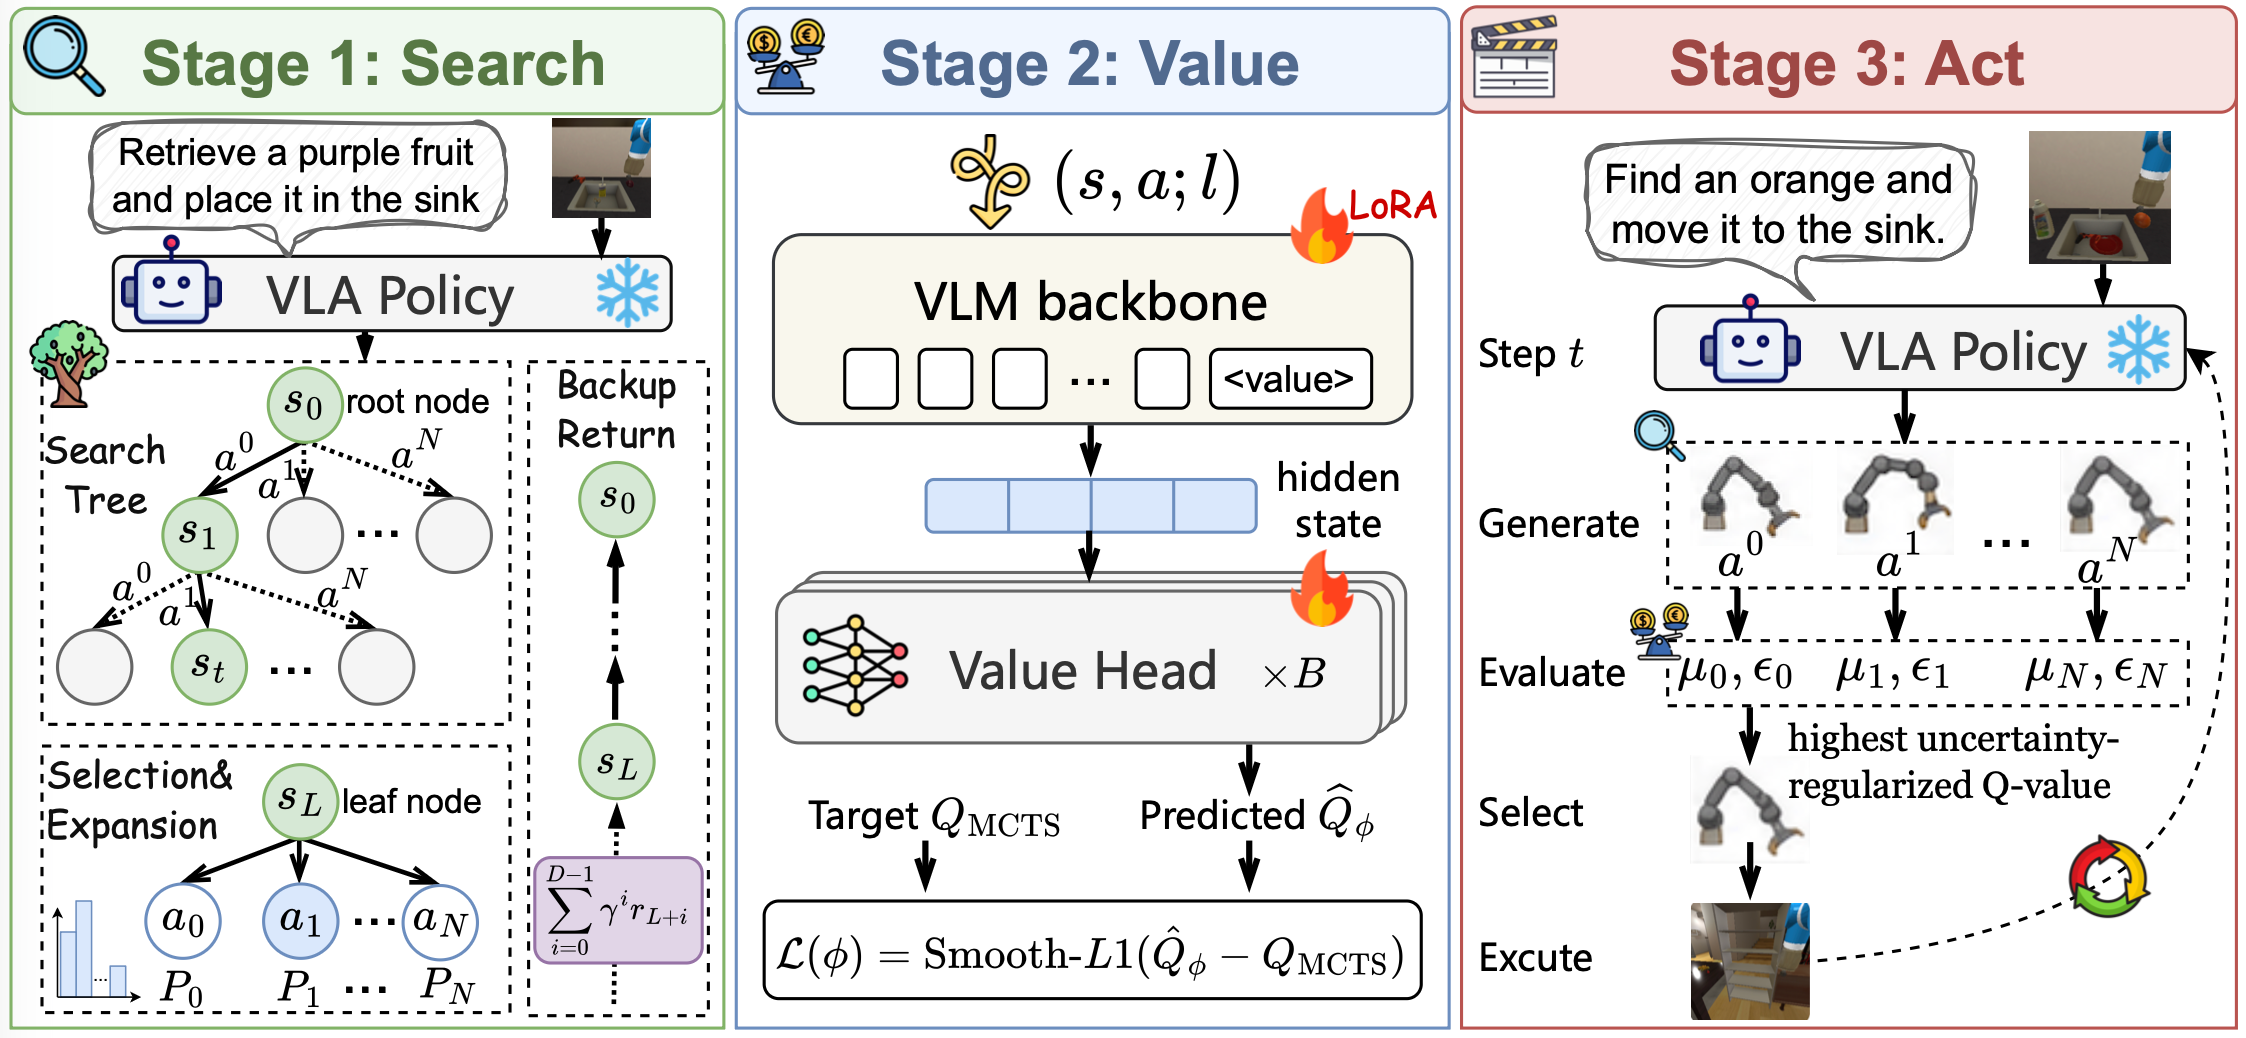
Proposes SVA (Search, Value, and Act), which keeps the VLA backbone frozen and equips it with long-term consequence awareness. Monte-Carlo tree search explores the policy's output distribution in simulation and is distilled into a lightweight Q-value evaluator that selects the best of N candidate actions at deployment without simulator access.

🎮 In-Context and Meta Reinforcement Learning

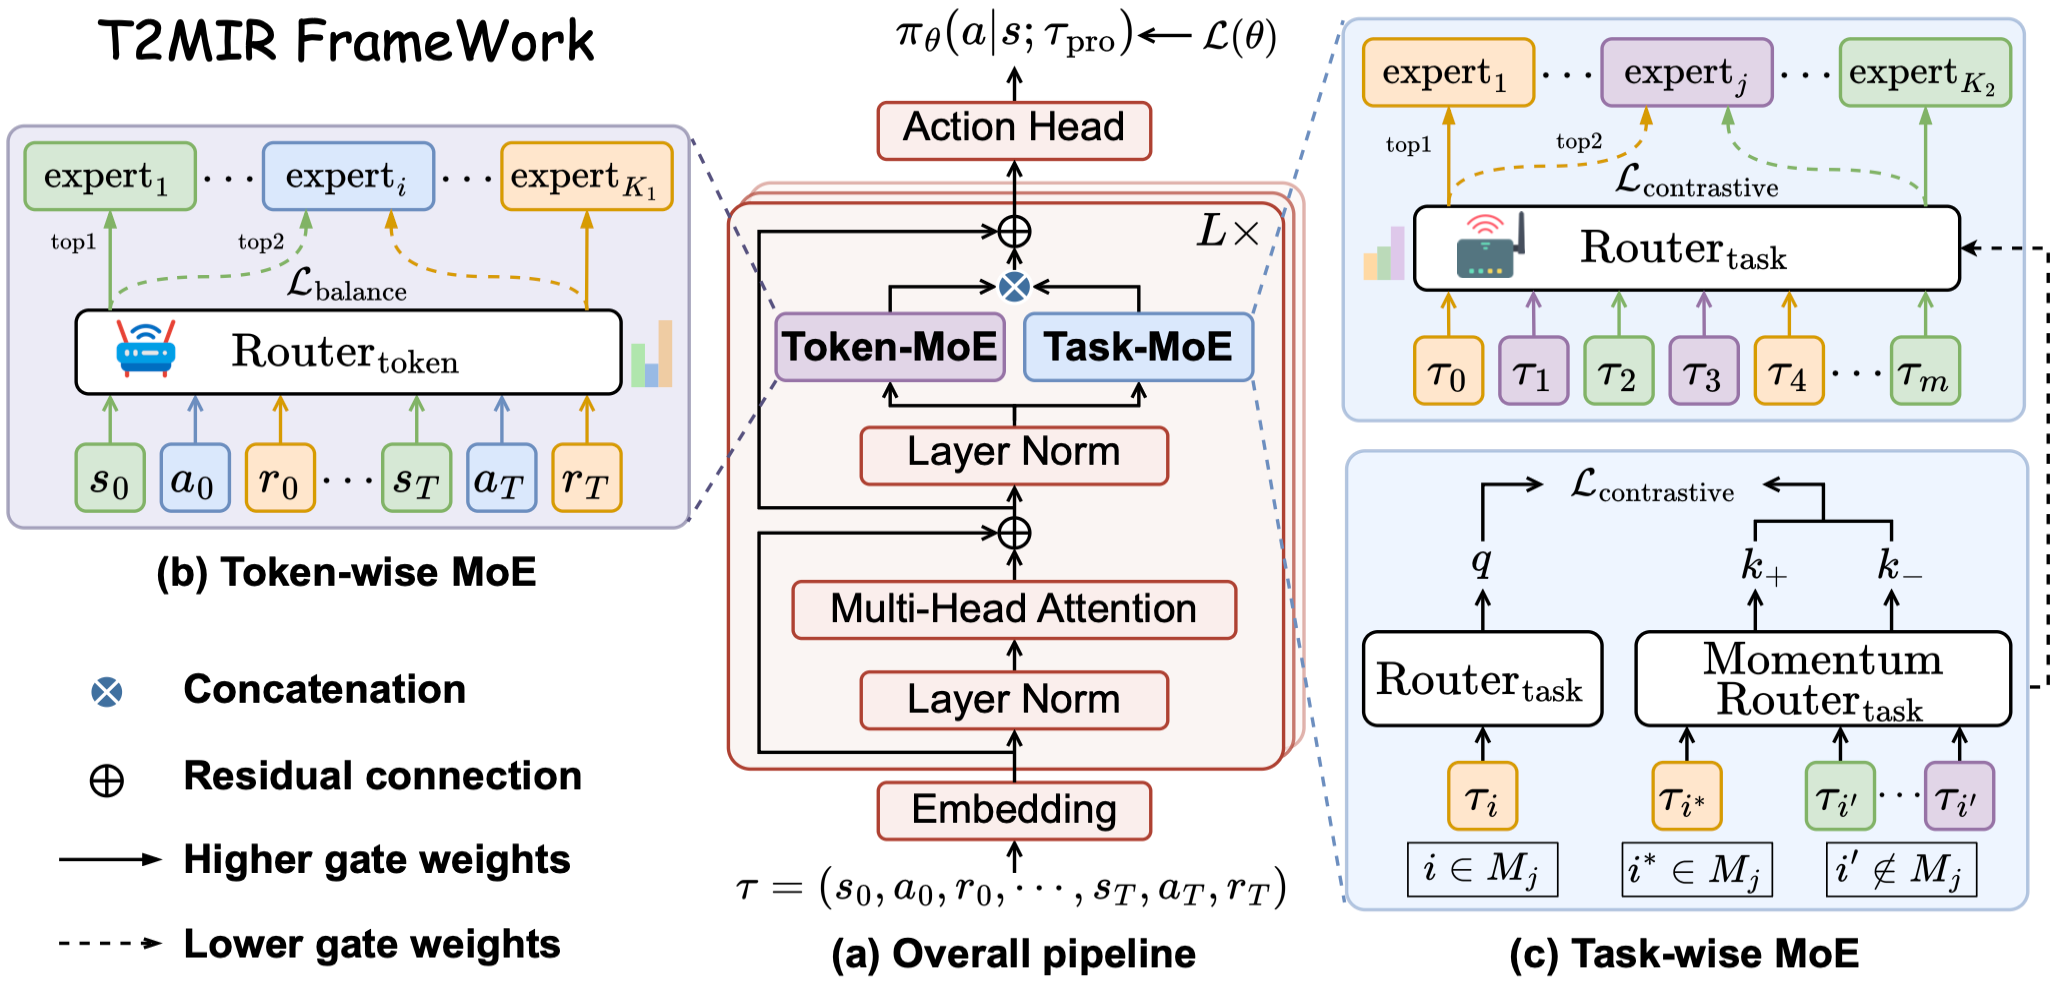
Mixture-of-Experts Meets In-Context Reinforcement Learning
Wenhao Wu, Fuhong Liu, Haoru Li, Zican Hu, Daoyi Dong, Chunlin Chen, Zhi Wang

Introduces a dual-MoE architecture for in-context RL. Token-wise MoE routes state, action, and reward information to specialized experts, while Task-wise MoE uses contrastive task representations to reduce gradient conflict in multi-task learning.

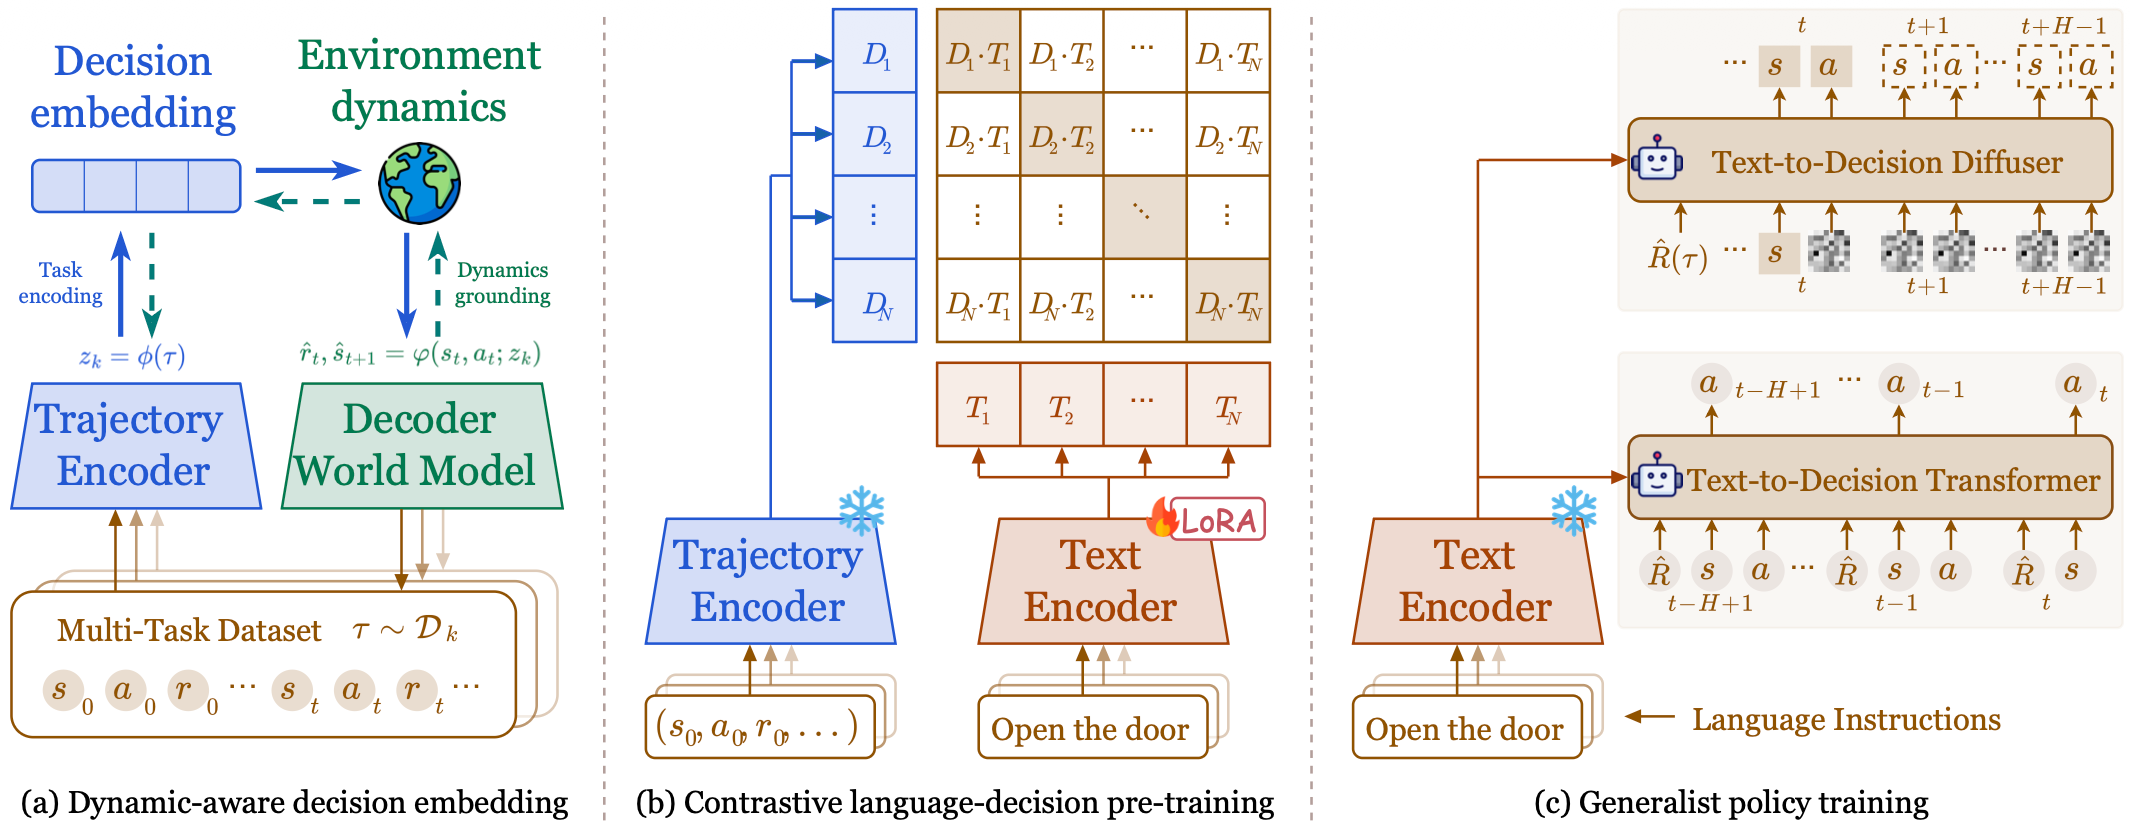
Text-to-Decision Agent: Offline Meta-Reinforcement Learning from Natural Language Supervision
Shilin Zhang*, Zican Hu*, Wenhao Wu*, Xinyi Xie, Jianxiang Tang, Chunlin Chen, Daoyi Dong, Yu Cheng, Zhenhong Sun, Zhi Wang

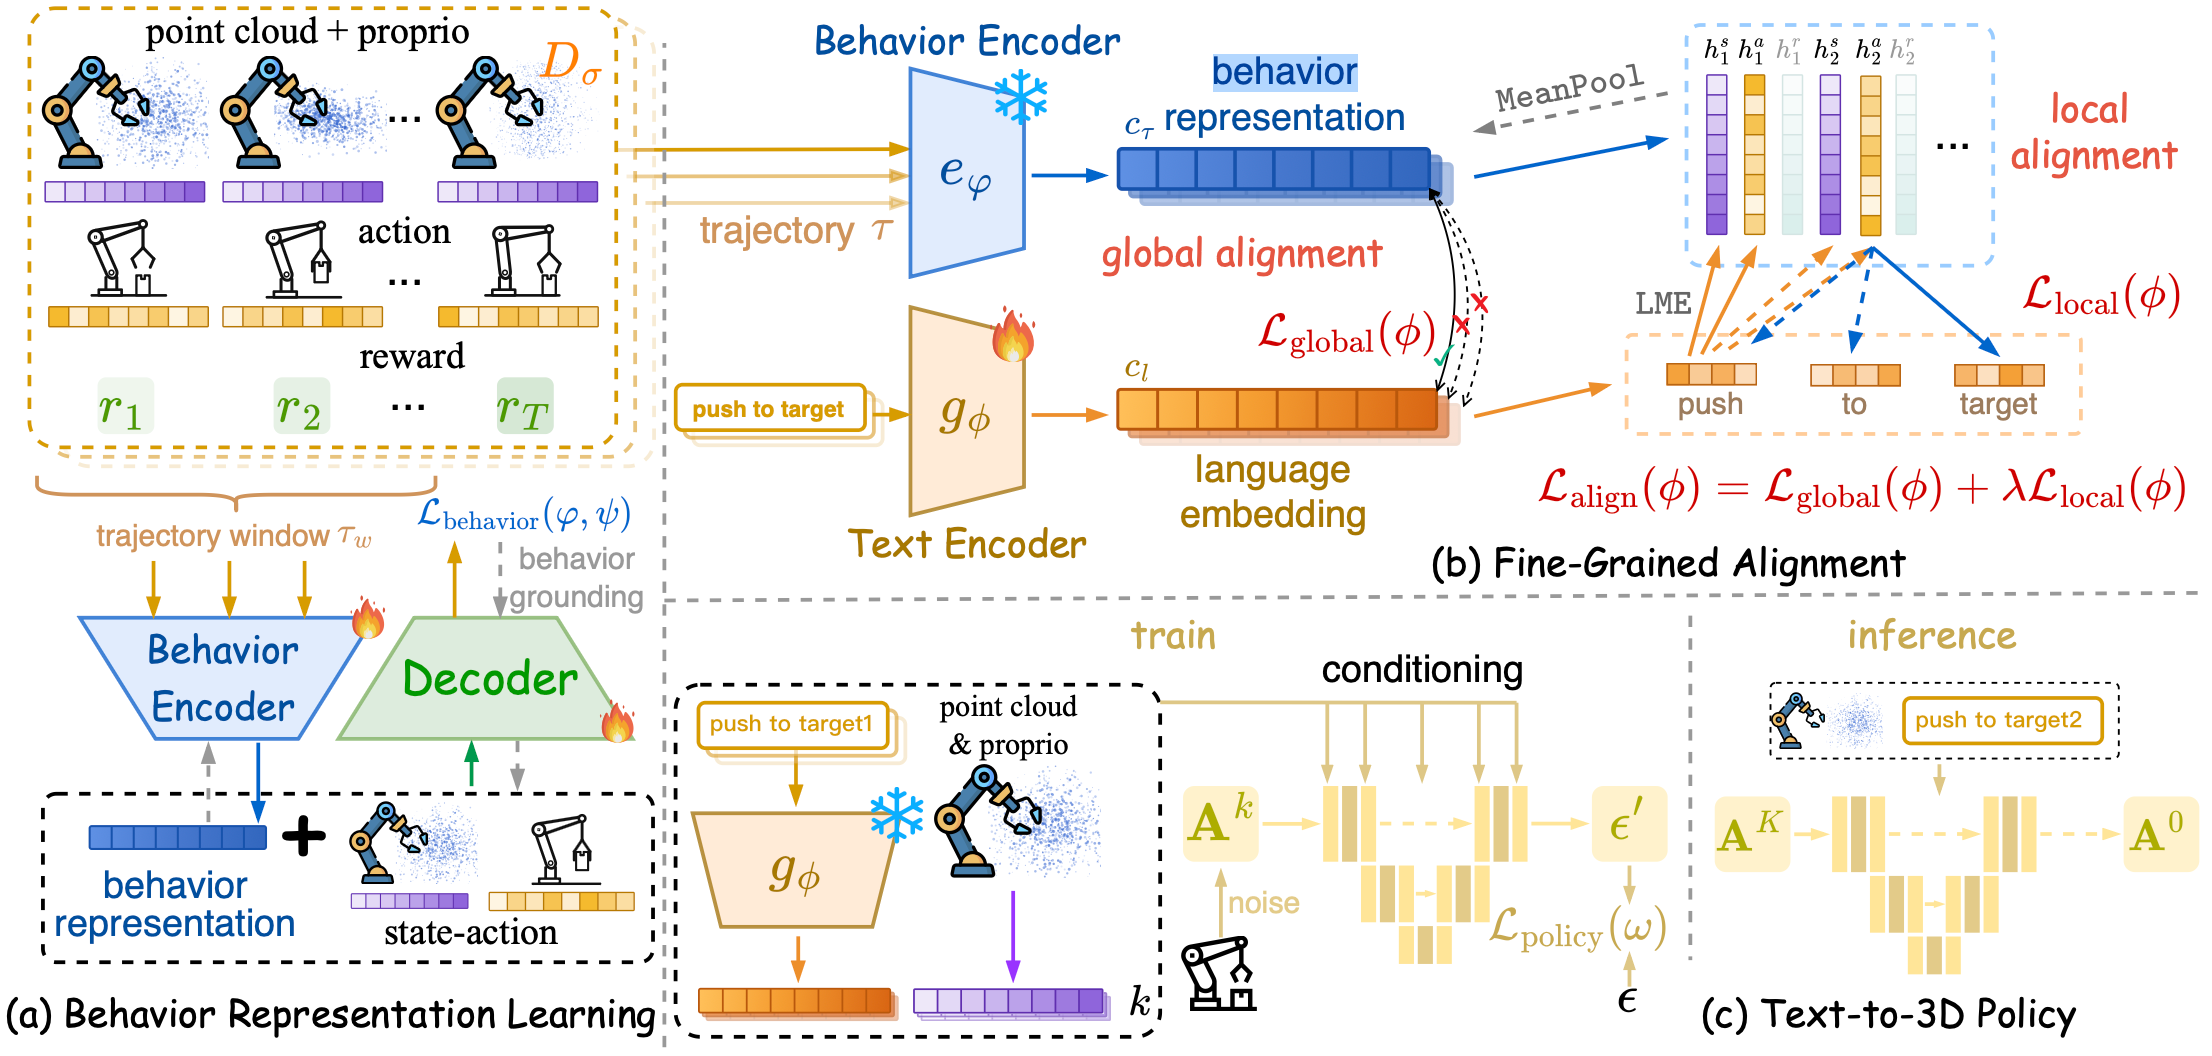
Aligns trajectory-derived decision embeddings with natural-language supervision. The framework trains a trajectory world model, performs contrastive alignment with LoRA-tuned language models, and conditions scalable policies on aligned text embeddings for zero-shot generalization.

🏁 Competitions

CAR-bench Challenge — Open Track
IJCAI-ECAI 2026 Competition Track · Darwin Agent team
Wenhao Wu*, Menghao Zhang*, Xin Wang*, Zhi Wang, Kun Shao, Jian Luan

Developed TRACE, a self-evolving Skill Bank for consistent and limit-aware LLM agents. Our team won both the Rank Award and Innovation Award, ranking 1st in the Open Track on the official hidden-set evaluation.

🎓 Education

  • 2024.09 - present: Nanjing University, M.Eng. in Control Engineering, School of Management and Engineering.
  • 2020.09 - 2024.06: Nanjing University, B.Eng. in Automation, School of Management and Engineering.

💼 Internships

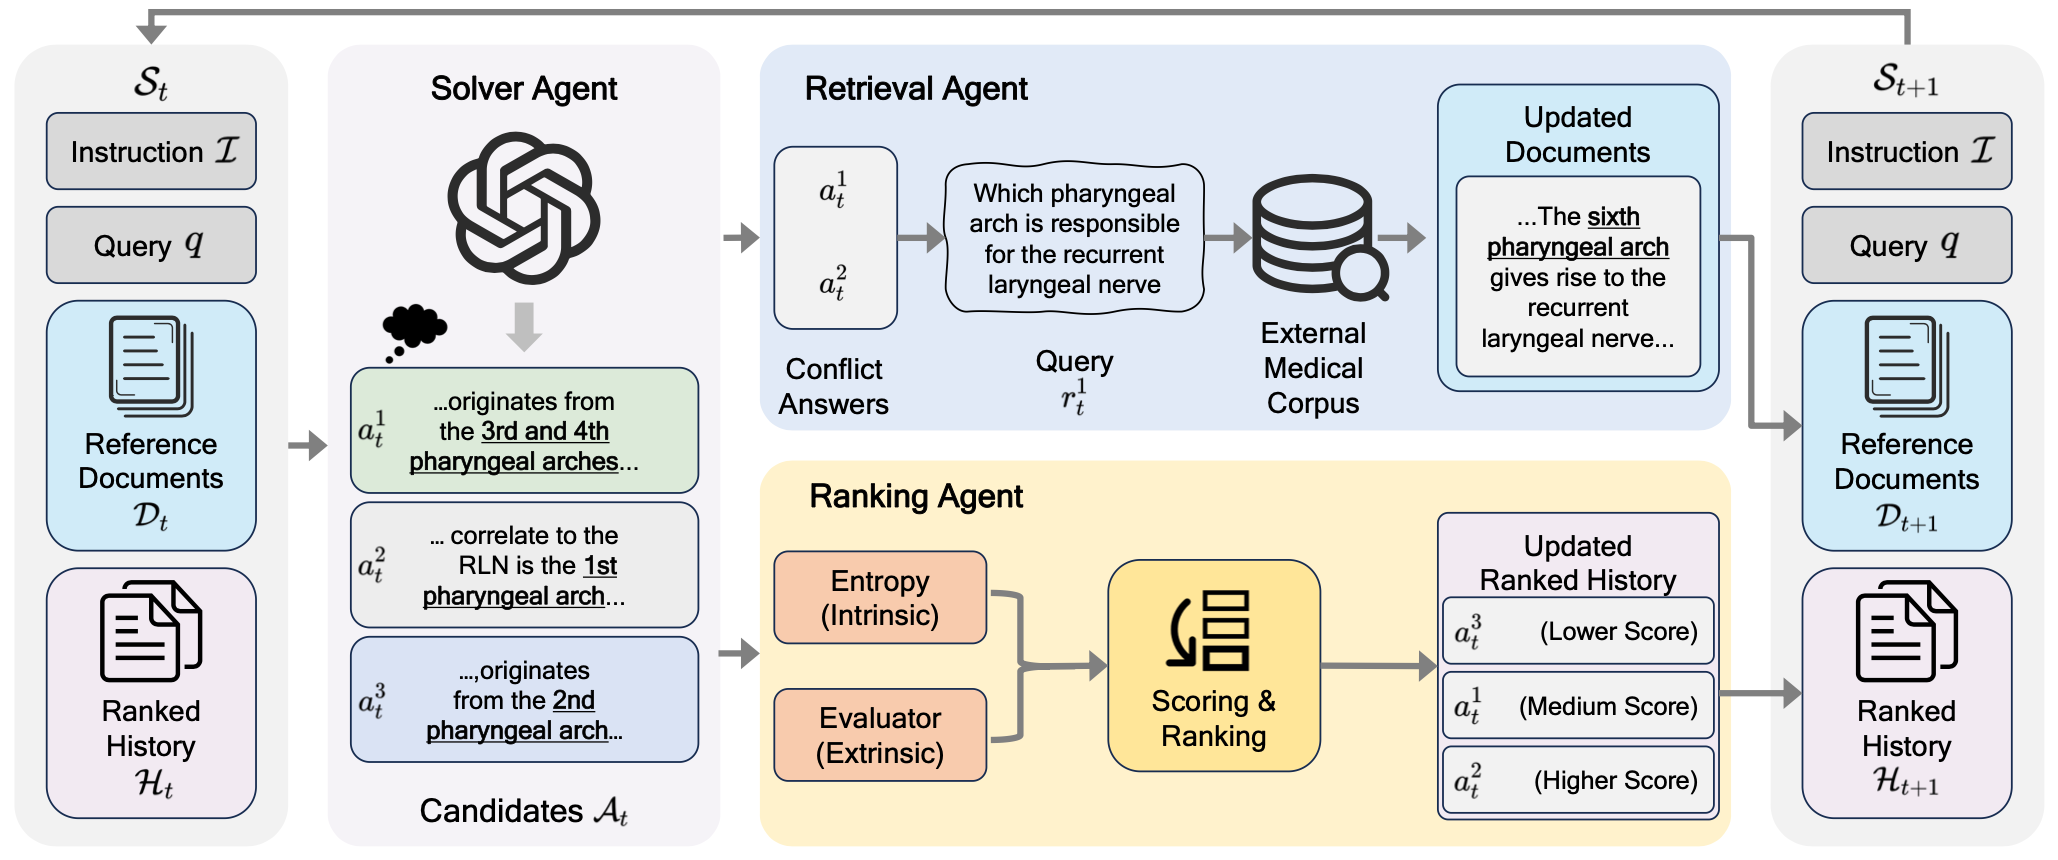
  • 2025.07 - 2026.01: Huawei Noah's Ark Lab, research intern. Worked on retrieval-augmented generation for medical question answering, medical knowledge retrieval services, conflict-guided adaptive retrieval, BERT-based answer reranking, adaptive stopping, and agentic RL for medical reasoning.

🏆 Awards

  • People's Scholarship, Nanjing University (2 times).
  • First-Class Academic Scholarship for master's students (2 times).
  • High-value scholarship (1 time).

🛠️ Academic Service

  • Gold Reviewer, ICML 2026.
  • Reviewer, NeurIPS 2026.